rag-notas
Assistant that answers questions about technical documentation in Spanish from the chunks it retrieves, with citations. Each stage is built first without frameworks and measured before moving on to the next one.
Answer questions about technical documentation in Spanish, citing where each answer comes from, and know with numbers whether it really works.
- Type
- Personal project
- Status
- In progress, updated in October 2026
- Areas
- AI, Backend
- Technologies
- Python
- ChromaDB
- sentence-transformers
- multilingual-e5-large
- bge-reranker-v2-m3
- Ollama (qwen2.5:14b)
Interactive demo
Screenshots
What it does
- Corpus of 20 public documents (Kubernetes, Pro Git and MDN), about 50,000 words
- Chunking by Markdown sections into 800-character chunks with a 100-character overlap
- Vector search with local embeddings and a cross-encoder reranker over 25 candidates
- Answers with [n] citations and a fixed sentence when the answer is not in the documents
- Own evaluation with 28 hand-written questions, including 5 with no answer in the corpus
What I learned
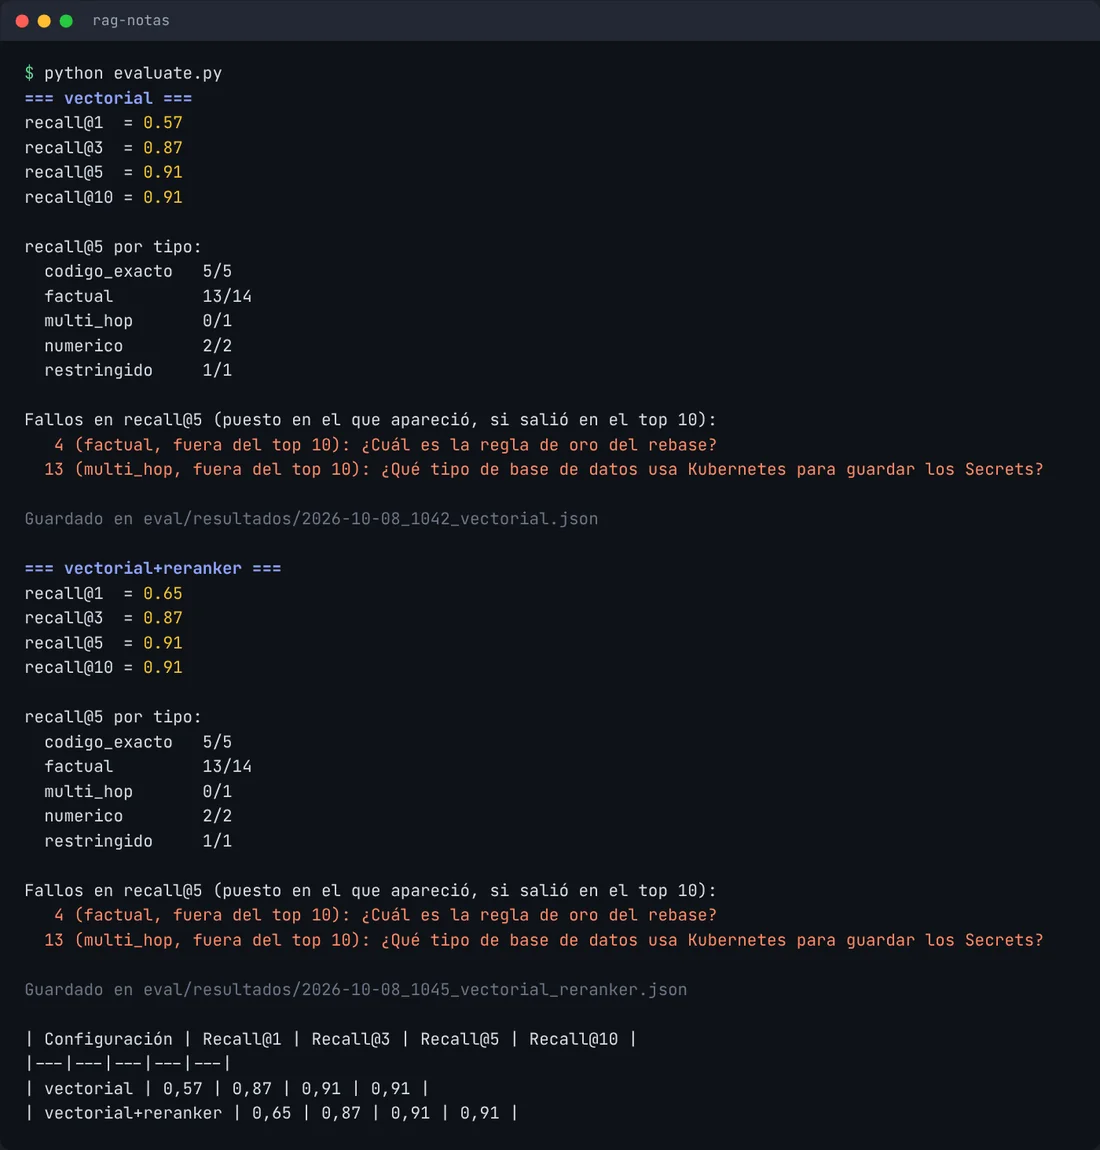
- Measure before optimising: the reranker raises recall@1 from 0.57 to 0.65 but does not change recall@5 (0.91)
- Failures are usually in retrieval: the Spanish translation of Pro Git says «reorganizar», not «rebase»
- A local LLM served from another machine on the network, with the firewall closed because Ollama has no authentication
- Testing the system against prompt injection with a trap document
In progress: answer quality still has to be evaluated and hybrid search added. The demo searches a real excerpt of the corpus with BM25 in the browser; the project uses vector search and an LLM that cannot run here.
Technical decisions
- Local multilingual-e5-large embeddings
- The documents are in Spanish and never leave the machine.
- Two-step chunking
- First by headings and then into 800-character chunks, so each chunk belongs to a single section.
- Section path at the start of each chunk
- The chunk keeps its context even when it is retrieved on its own, for example «Pods > Uso de Pods».
- Reranker over 25 candidates
- Gains 0.08 recall@1 at the cost of about 8 seconds per query on CPU; with a GPU the cost would drop a lot.
- Local LLM with Ollama on another machine on the network
- No cost per query. The firewall only lets the development machine in, because Ollama has no authentication.
- A prompt that allows saying «I don't know»
- It only uses the context, with a fixed sentence when there is no answer and [n] citations that make the answer verifiable.
How it's built
Click each piece to see what it does.
Public documentation from Kubernetes, Pro Git and MDN in Spanish, stripped of markup and converted to Markdown. About 50,000 words.
Splits first by headings and then into 800-character chunks with a 100-character overlap. Each chunk carries its section path at the front so it keeps its context.
Stores the multilingual-e5-large embeddings, computed locally, and returns the 25 chunks closest to the question.
bge-reranker-v2-m3 reorders those 25. It raises recall@1 from 0.57 to 0.65 at the cost of about 8 seconds per query on CPU.
qwen2.5:14b on Ollama, served from another machine on the network. It may only use the context, cites with [n], and citations to chunks that do not exist are detected afterwards.